A CNN building block for small objects and low-resolution images (ECML PKDD 2022)
Strided convolutions and pooling throw away fine detail every time a CNN downsamples. That hardly matters on large, clean images, but it hurts on small objects and low-resolution inputs.
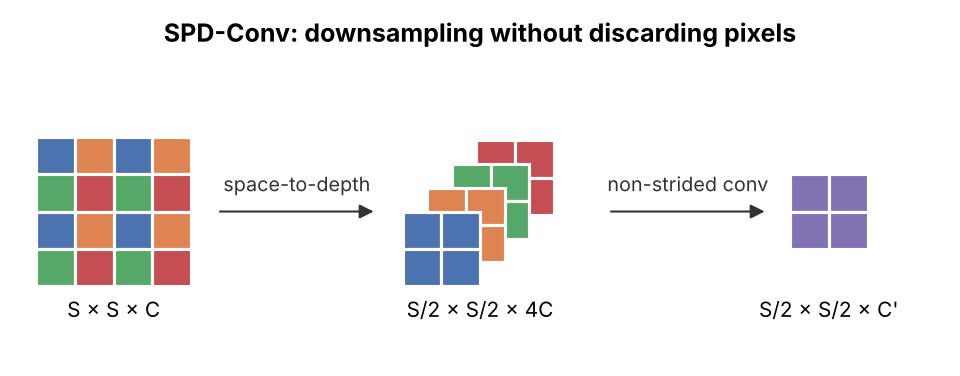
SPD-Conv replaces each of these layers with a space-to-depth step, which moves every 2×2 block of pixels into the channel dimension so nothing is discarded, followed by a non-strided convolution. It drops into most CNNs. In the paper, YOLOv5-SPD and ResNet-SPD outperform their baselines on small objects and low-resolution images, and the block is now widely used in YOLO-based detectors.
Convolutional neural networks lose fine-grained information through strided convolutions and pooling layers. This hurts badly on harder tasks such as low-resolution images and small objects. SPD-Conv replaces each strided convolution or pooling layer with a space-to-depth (SPD) layer, which rearranges every 2×2 block of pixels into channels without discarding anything, followed by a non-strided convolution. The block is general and drops into most CNN architectures. Applied to YOLOv5 (object detection) and ResNet (image classification), it clearly outperforms state-of-the-art models on low-resolution images and small objects.
@inproceedings{sunkara2022no,title={No More Strided Convolutions or Pooling: A New {CNN} Building Block for Low-Resolution Images and Small Objects},author={Sunkara, Raja and Luo, Tie},booktitle={Joint European Conference on Machine Learning and Knowledge Discovery in Databases (ECML PKDD)},series={Lecture Notes in Computer Science},volume={13715},pages={443--459},year={2022},publisher={Springer},doi={10.1007/978-3-031-26409-2_27},}